Engines and the home directory
from cereyan import flow

@flow(isolated=True)
def heavy() -> str:
    return "fresh process every time"

assert heavy.options["isolated"]
Cereyan has two execution paths that write the same store with the same rules.
offline                              served
───────                              ──────
python pipeline.py                   cereyan serve dir/
  │ runs in-process                    │ imports every module under dir/
  │ writes db.sqlite directly          ├── HTTP API + UI + MCP
  │ under an OS advisory lock          ├── scheduler (timer heap)
  ▼                                    ├── rules engine
db.sqlite                              └── supervisor ──▶ engine processes
  ▲                                                        (one module each, warm,
  └─── while a server holds the lock, a script hands ────── report over loopback HTTP)
       its run to the server and streams the logs back
The offline path
python pipeline.py and cereyan run execute the flow in the current process and write runs, task runs, logs, events, and artifacts straight into db.sqlite, holding db.lock while they do. Nothing else needs to run. If a server holds the lock, the script cannot take it; it reads server.json, submits the run to the server with the module and directory to import, and streams the logs back to the terminal until the run ends. That handoff works across projects, so a script in one directory can run through a server started in another.
The served path
cereyan serve dir/ is one process hosting the HTTP API, the UI, the scheduler, the rules engine, the MCP endpoint, and the supervisor, which keeps a warm pool of engine child processes.
- Each engine is bound to one Python module, imports it once, and executes runs of its flows one at a time. Because the import happens once, module-level state — an HTTP client and its connection pool, a warmed cache — is shared by every run that engine serves; see fetching from an HTTP API. Engines are keyed by
(source_dir, module), wheresource_diris the directory the module imports from (the served directory, for a flow in a sub-folder), and pooled up tomax_engines, which the UI calls processors (default: 1, at most the machine's CPU count). - An engine is recycled after
engine_max_runsruns (default 100) or when its module file changes, so edits are picked up without restarting the server.@flow(isolated=True)gives every run of that flow a fresh process, terminated afterwards. - Engines report task-run transitions and logs in batches every 100 milliseconds (immediately on flow-level transitions) over one keep-alive connection, and heartbeat every five seconds per active run. Three missed heartbeats and a dead PID mark the run
Crashed; it is rerun up tocrash_retriestimes. - Cancelling a run moves it to
Cancelling, tells the engine, waitscancel_grace_secs, sends SIGTERM, waits again, then SIGKILL. The engine raisesKeyboardInterruptin the flow so it can clean up. It reaches Python code andtime.sleepon every platform; on Windows it cannot reach most blocking I/O, so a flow waiting there runs until the supervisor ends the process, which Windows does abruptly in place of SIGTERM. - Engines survive a server restart: on start the supervisor adopts runs whose engine PID is still alive and waits for the engine to reconnect; runs whose engine is gone are marked
Crashedwith the reason. - Stopping the server ends its engines. While shutting down it answers every waiting engine with an instruction to exit, then signals any that were between requests; an engine executing a run is left running so a restarted server can adopt it. An engine that loses its server without being told to stop — a kill, a crash — exits by itself: about thirty seconds when the server refuses connections outright, and within forty in the worst case, since it can only notice between requests and a request waits that long before giving up. One exception: an engine still reporting a run it has just finished keeps trying for up to ten minutes, so that a server restarted in the meantime records the outcome rather than seeing a crash.
- An engine that fails to import its module fails every run assigned to it with the traceback, and the flow shows the error in the API and the UI.
Processors and the queue
Every run the server starts waits in one queue, whatever made it: a schedule, a rule, the API, an agent, a backfill. A free engine takes the first run in line that can start, ordered by priority and then by how long it has waited. A run blocked by a resource or a cap is passed by later runs that can start, and the Queue page says so. When the first run that can start belongs to a module with no free engine and the pool is full, a free engine of another module exits to make room rather than take a later run of its own module, so a deep backfill of one module cannot hold up another.
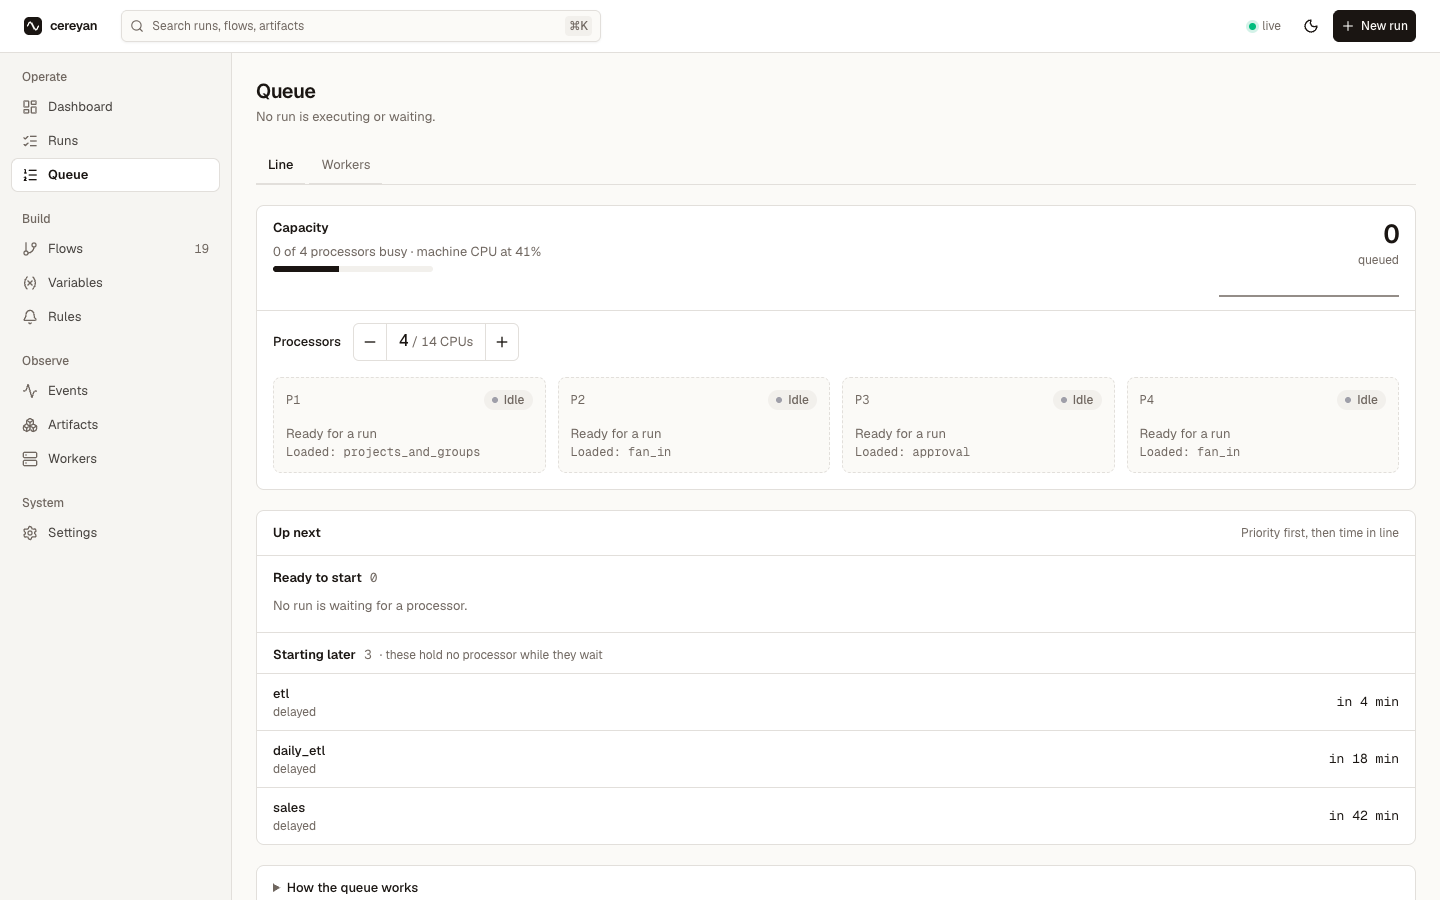
The Queue page shows the pool as processors: add or remove them there, or with PATCH /api/settings {"max_engines": n}. The change applies at once and is written to [server] max_engines. Removing a busy processor never interrupts its run: it is marked draining, finishes the run, then exits. The count cannot go above the machine's CPU count, so work that mostly waits on the network gets its parallelism from concurrent tasks inside a run rather than from more processors. A new server starts with one processor; --max-engines, [server] max_engines, or the Queue page raise it.
The Settings page lists the engines with their PID, module, runs done, and current run.
Workers on other machines
cereyan worker --host URL on another machine adds that machine's processors to the same queue. The worker imports its own checkout of the project, registers the flows it can run with a fingerprint of each module, and starts engines when the server asks. Those engines take runs over the same protocol as the server's own: a run goes to a worker only when the server's processors are full, the flow does not say runs_on="server", and the worker's code for the module matches the server's. Results, checkpoints and secrets stay on the server; the worker's engines never open a store of their own. The Queue › Workers tab lists every worker with its status, host, processors, and the runs it executed. See Run across machines.
The home directory
One runtime home per machine holds everything: db.sqlite, db.lock, server.json while a server runs, secret.key once a secret exists, token once a server bound beyond loopback has generated its API token, and storage/ for persisted results. Only the account that created it can read it, which is what protects the store and the key alike. It resolves from --home, then CEREYAN_HOME, then ~/.cereyan; cereyan.toml cannot move it, so a repository can never point the store elsewhere. Engine children inherit it through CEREYAN_HOME.
Because the home is global, one server runs per machine and holds the advisory lock. History is a cache: losing db.sqlite loses the run list, not your data, which lives in your targets. A corrupted database is quarantined and a fresh one created.
Performance shape
The store is SQLite in WAL mode with one writer thread and group commit, a read pool, and an in-memory working set (active runs, counters, the schedule heap, resources, the rule index). Engine reports are serialised in Rust. The targets, such as 20k task transitions per second and a runs list under 10 ms at a million runs, are on the Performance targets page.
Related: Run the server as a service, Secure the server, Exit codes and the discovery file.